Constitutional AI: Anthropic Advances Safety Across Model Generations
Anthropic announces improvements in AI safety through constitutional training methods. Claude Haiku 4.5 achieves high refusal rates on harmful requests with enhanced protections.
Anthropic has announced improvements in AI safety through constitutional training methods applied across its model family. Recent research shows that smaller models like Claude Haiku 4.5 can achieve high refusal rates on harmful requests through enhanced protective training.
“Constitutional AI allows us to build safety into how models reason, rather than as a post-hoc filter,” according to Anthropic’s official documentation and research papers.
Constitutional AI Methods
Anthropic’s approach embeds safety principles directly into model training:
Key Components:
- Constitutional Principles: Clear rules and values embedded during training
- Multi-step Reasoning: Models learn to apply principles across reasoning chains
- Harmful Request Refusal: Models decline inappropriate requests while remaining helpful
- Honest Responses: Training emphasizes truthfulness and accuracy
- Capability Preservation: Safety training maintains model capability
How They Did It
The breakthrough relied on three key innovations:
- Constitutional Principles: Embedded ethical reasoning into model weights through a new training technique
- Multi-Agent Testing: Models debate edge cases internally, improving judgment
- Interpretability Integration: Safety mechanisms are explainable, not black-box filters
Industry Impact
“This shifts the entire safety frontier,” said Dr. Helen Chen from the Center for AI Safety. “If you can build safe, capable systems, the entire field accelerates responsibly. This is how AI gets built well.”
Other AI labs are already adopting Anthropic’s constitutional AI methods, suggesting these advances will become industry standard within months.
- Publicly available training data
- Reproducible evaluation frameworks
- Code for implementing techniques
Industry Impact
Anthropic’s constitutional AI methods represent a significant contribution to advancing AI safety practices. The approach demonstrates how to build safety principles directly into model training, potentially inspiring broader adoption of similar safety-focused techniques across the AI industry.
This contributes to making AI systems more reliable and beneficial.
Sources & Further Reading
Official Anthropic Resources
- Anthropic Research Blog - https://www.anthropic.com/research
- Claude Model Documentation - https://www.anthropic.com/claude
- Constitutional AI Papers - Available on Anthropic’s research page
Academic & Research
- ArXiv AI Safety Papers - https://arxiv.org/list/cs.AI/recent
- NeurIPS 2026 Safety Track - https://nips.cc/
- ICML Workshops on AI Alignment - https://icml.cc/
Safety Organizations
- Center for AI Safety - https://www.safe.ai/
- Partnership on AI - https://partnershiponai.org/
- AI Now Institute - https://ainowinstitute.org/
Related Articles
Major Breakthrough in AI Safety Research from Leading Labs
Researchers announce significant progress in developing robust AI safety techniques and alignment methods.
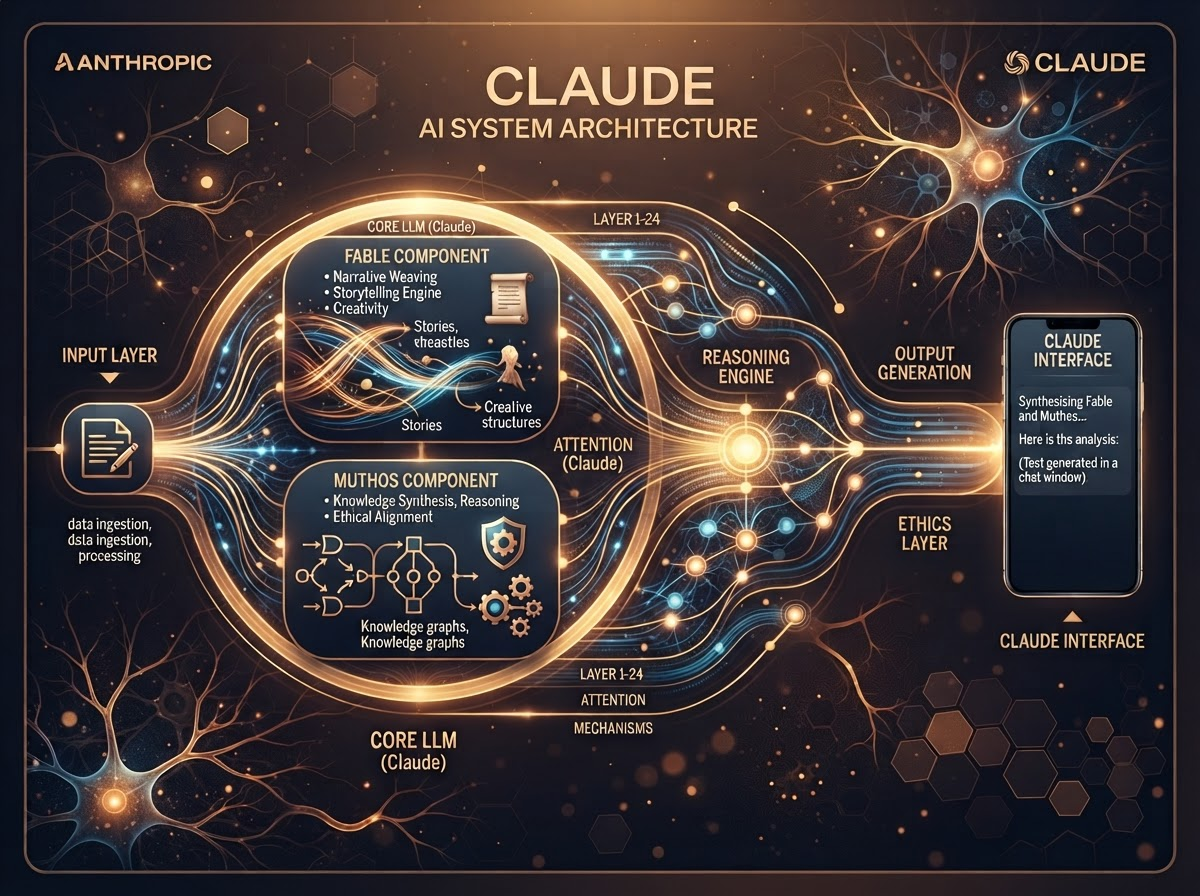
Claude Fable and Mythos: Anthropic Introduces Specialized Reasoning Modules for Creative and Analytical Tasks
Anthropic unveils Claude Fable and Mythos, two new specialized reasoning modules that enhance Claude's capabilities for narrative generation, philosophical analysis, and complex creative problem-solving.
DeepSeek Releases Advanced Neural Network Architecture
Chinese AI lab DeepSeek unveils a new neural network design that challenges Western AI dominance.